Generative Engine Optimization Tools for AI Search
Compare generative engine optimization tools for tracking AI citations, auditing content, researching prompts, and improving visibility in AI search.
Original illustration by GeniuzQuiz
Generative engine optimization tools measure how brands, products, and pages appear in answers from ChatGPT, Google AI Overviews, Gemini, Perplexity, and similar systems. The best setup combines an AI visibility tracker, conventional SEO data, analytics, and manual answer verification. No single platform reliably handles prompt research, citation analysis, content improvement, and revenue attribution.
Generative engine optimization, or GEO, is the practice of making accurate, useful content easy for AI systems to retrieve, understand, cite, and recommend. A GEO tool should therefore do more than count brand mentions: it should show which prompts matter, which sources influence answers, what changed, and what action to take next.
Key takeaways
- Use a dedicated AI visibility platform when you need repeatable prompt tracking, citation monitoring, and competitor comparisons.
- Keep conventional SEO tools in the stack because crawlability, indexing, links, entities, and page quality still affect source selection.
- Measure citations, attributed mentions, answer position, source diversity, and qualified traffic rather than relying on one visibility score.
- Segment prompts by audience, intent, market, and buying stage. A large generic prompt list produces misleading averages.
- Validate automated reports manually because AI answers vary by model, location, personalization, retrieval mode, and time.
- Connect AI visibility to business outcomes such as quiz starts, lead quality, demos, and assisted conversions.
What do generative engine optimization tools actually do?
GEO tools repeatedly submit or model relevant prompts, capture the generated answers, and analyze those answers for brand mentions, links, citations, competitors, sentiment, and themes. More advanced products also identify the domains and pages most frequently used as sources, monitor changes over time, and recommend content improvements.
This category overlaps with rank tracking, social listening, digital PR, entity SEO, and answer engine optimization. The distinction is the unit being measured. A traditional rank tracker follows a URL's position for a keyword. A GEO tracker examines a generated response that may mention several brands, cite multiple sources, contain no visible blue links, or change when the same question is asked again.
The tools generally perform five jobs:
- Prompt monitoring: Run a defined set of questions across one or more AI answer engines on a schedule.
- Answer capture: Save the response, cited URLs, linked domains, date, model, and other available context.
- Entity analysis: detect whether the brand, product, founder, category, or competitor appears and how it is described.
- Source analysis: Identify publishers, communities, product pages, documentation, and third-party reviews that influence the answer.
- Reporting: Turn observations into trends, competitor comparisons, alerts, and recommended actions.
Not every platform obtains its data in the same way. Some run live prompts through consumer interfaces or supported APIs. Some use sampled datasets or proprietary indexes. Others analyze Google result features, including AI Overviews, rather than responses inside standalone assistants. These methods can produce different results even when dashboards use similar labels such as visibility, share of voice, or citation share.
That is why a visibility percentage should never be accepted without a denominator. Ask which prompts, engines, countries, devices, model versions, and dates are included. A brand mentioned in 30 of 100 tracked answers has a 30% mention rate for that monitored set, not a 30% share of all AI conversations.
For teams using a quiz funnel as a lead magnet, GEO monitoring can answer practical questions. Does an assistant recommend the quiz for a relevant problem? Does it cite the landing page, a supporting guide, or a third-party list? Does the answer correctly describe what the quiz does? Those details matter more than a broad score because they affect whether a qualified person reaches the funnel.
Which GEO tools should you use for AI search visibility?
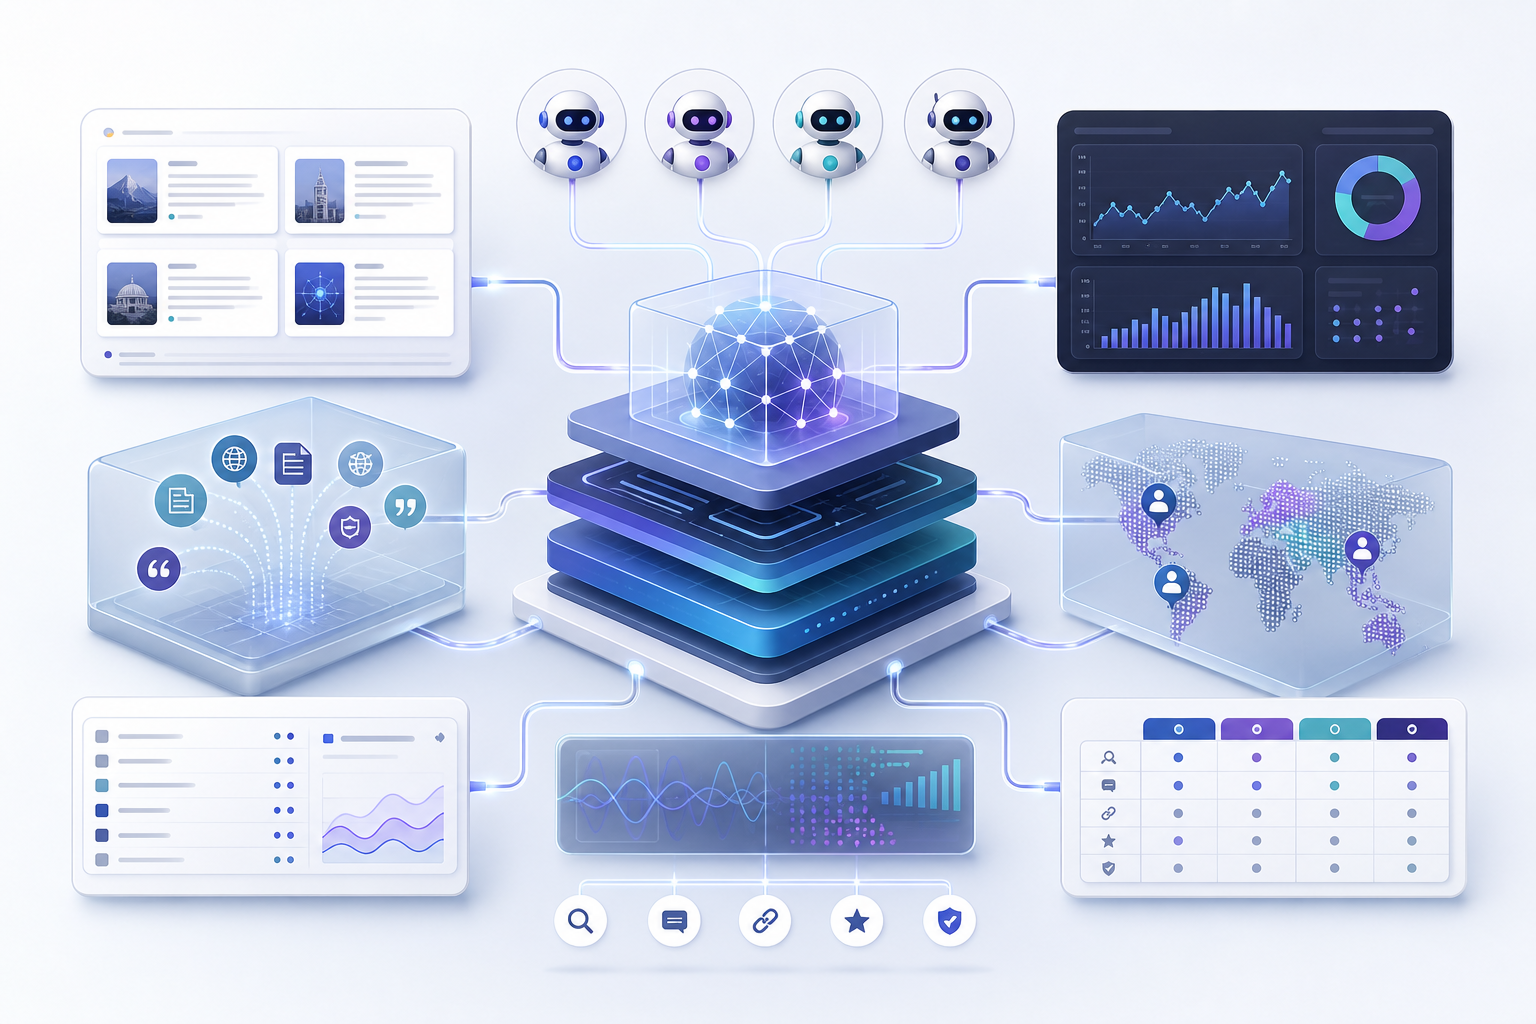
The right choice depends on whether the team needs enterprise governance, an agency workflow, affordable monitoring, SEO integration, or raw data for custom analysis. Product capabilities change quickly, so verify current engine coverage, geographic support, data retention, API access, and prompt limits during a trial.
| Tool or tool type | Best use | Useful capabilities to evaluate | Main tradeoff |
|---|---|---|---|
| Profound | Enterprise AI visibility and content intelligence | Answer monitoring, citation analysis, competitive views, source insights, and enterprise reporting | May be more platform and budget than a small team needs |
| Scrunch AI | Brand presence, customer journey analysis, and AI readiness | Visibility monitoring, brand representation, journey insights, and site-oriented recommendations | Teams still need SEO and analytics tools for a complete workflow |
| Peec AI | Focused brand and competitor tracking | Prompt monitoring, visibility trends, source analysis, and accessible competitive reporting | Coverage and workflow depth should be tested against specific markets |
| Otterly.AI | Practical monitoring for smaller teams and agencies | Prompt tracking, links, citations, brand mentions, and scheduled reporting | Reporting needs may outgrow a lightweight implementation |
| ZipTie.dev | AI search monitoring with an SEO-oriented workflow | AI Overview and assistant visibility, citations, mentions, and query tracking | Fit depends on the engines and regions most important to the business |
| Semrush AI visibility products | Teams already working inside Semrush | AI visibility, competitor research, prompt insights, and connection to broader SEO data | Convenience does not eliminate the need to inspect captured answers |
| Ahrefs Brand Radar and related data | Brand discovery and web-scale comparison | Brand mentions, competitive research, search demand context, links, and content discovery | Use cases and metrics differ from a dedicated prompt-by-prompt tracker |
| SE Ranking AI visibility features | Agencies combining client SEO and AI reporting | Monitoring, competitive data, reporting, and integration with established SEO workflows | Confirm the precise AI surfaces and export options included in the selected plan |
| Google Search Console and analytics | Traffic, landing-page, and conversion validation | Search performance, page discovery, referral traffic, events, and revenue attribution | They do not reveal the full set of unclicked AI mentions or prompts |
| Custom LLM API workflow | Teams needing controlled prompts and raw data | Custom sampling, structured outputs, warehousing, scoring, and internal integrations | API responses may not match consumer products and require engineering maintenance |
Profound and Scrunch AI are logical candidates when AI visibility is an organization-wide concern involving several products, markets, and stakeholders. Enterprise buyers should focus on permissions, audit history, warehouse exports, regional tracking, security, and the ability to inspect evidence behind summary metrics.
Peec AI, Otterly.AI, and ZipTie.dev are worth evaluating when the primary need is to monitor prompts, citations, and competitors without deploying a broad enterprise suite. The deciding factor should not be the prettiest dashboard. Run the same representative prompt set in each trial and compare captured responses, source detail, exports, filters, and alert quality.
Established SEO vendors such as Semrush, Ahrefs, and SE Ranking can reduce workflow fragmentation. Their conventional datasets remain valuable because AI visibility is connected to discoverability on the open web. Strong pages still need to be crawlable, internally linked, factually clear, and supported by relevant authority signals.
Do not remove Google Search Console, Bing Webmaster Tools, web analytics, or a crawler simply because a dedicated GEO platform has been purchased. Search Console helps determine whether supporting pages receive impressions and clicks. Analytics shows whether visitors engage. A crawler finds blocked resources, accidental noindex directives, broken canonicals, weak internal links, and rendering problems that a prompt monitor may never diagnose.
A custom workflow can be useful for organizations with data engineering resources. A script can send controlled prompts to supported model APIs, retain structured results, extract named entities and cited URLs, and load observations into a warehouse. However, an API result is not automatically representative of ChatGPT's consumer interface, Perplexity's retrieval behavior, Gemini, or Google AI Overviews. Treat each surface as a separate measurement environment.
How should you evaluate a GEO software platform?
Use the SIGNAL checklist: Scope, Intent, Grounding, Next action, Analytics, and Learning. A credible GEO platform covers the required search surfaces, tracks prompts that reflect real intent, preserves citation evidence, suggests a defensible next action, connects visibility with outcomes, and supports repeated learning over time.
1. Define the required scope
List the AI surfaces, countries, languages, product lines, and competitors that matter before requesting demos. Google AI Overviews are not interchangeable with ChatGPT, and an English-language result in the United States may not resemble a Spanish result in Mexico. Confirm whether the vendor runs live checks, estimates coverage, or combines both methods.
Ask how often prompts are checked and whether the schedule can be changed. Frequent sampling can expose volatility but increases cost and data volume. Weekly monitoring may be sufficient for stable category prompts, while product launches, reputation issues, and fast-moving news may justify daily checks.
2. Build an intent-based prompt test
Give every shortlisted vendor the same test set. Include educational, comparative, commercial, navigational, and troubleshooting questions. Add natural variations rather than swapping one keyword at a time. People prompt assistants conversationally, provide constraints, and ask follow-up questions.
A quiz software company might test prompts such as:
- How can I qualify leads before a sales call?
- What is the best quiz funnel builder for a small coaching business?
- Compare interactive quizzes with PDF lead magnets.
- Which quiz platform can personalize product recommendations?
- How do I connect a quiz funnel to Meta ads and email automation?
- What should I look for in an AI quiz builder?
Prompts should be tagged by persona and funnel stage. A marketing director comparing vendors has a different information need from a practitioner troubleshooting completion rates. Mixing both into one average conceals the pages and claims that require work.
3. Inspect grounding and evidence
The platform should retain enough evidence to reproduce an observation: prompt text, answer text, engine, date, cited domain, cited URL, and available market settings. Screenshots can help with audits, but searchable text and exports are more useful for analysis.
Check whether citations are resolved to canonical URLs and whether the tool distinguishes a linked citation from an unlinked brand mention. Also inspect source extraction manually. Redirects, tracking parameters, copied articles, syndicated content, and URL fragments can inflate the apparent number of unique sources.
4. Demand an actionable next step
A recommendation to “improve authority” is not operational. Useful software should help identify whether the gap is missing category coverage, an unsupported claim, weak entity clarity, absent comparison information, limited third-party corroboration, technical accessibility, or outdated facts.
The next step may not involve editing the target landing page. If AI answers consistently cite independent publications, communities, review sites, or documentation, the correct response might be digital PR, partner education, customer proof, or a better public knowledge base. GEO is partly an owned-content discipline and partly an information-distribution discipline.
5. Test analytics and exports
Confirm that observations can be exported at the answer, prompt, citation, URL, and date levels. Summary PDFs are insufficient for serious analysis. Teams should be able to join GEO data with CRM records, analytics events, content inventories, and release logs.
Review API limits, webhook support, scheduled exports, user permissions, and data retention. Agencies also need account separation and client-ready reporting. Enterprises may require single sign-on, procurement documentation, and controls for sensitive prompt sets.
6. Check whether the platform supports learning
A useful system records interventions. If a team updates a comparison page, publishes original research, fixes a crawling issue, or earns a third-party review, that change should be annotated against future visibility. Without an experiment log, normal answer volatility can be mistaken for the result of an optimization.
Run the evaluation for long enough to observe repeated answers. A single-day trial rewards noise. A better pilot uses a carefully tagged prompt set, several engines, at least two sampling periods, and manual checks of strategically important prompts.
How do you build a practical GEO tool stack?
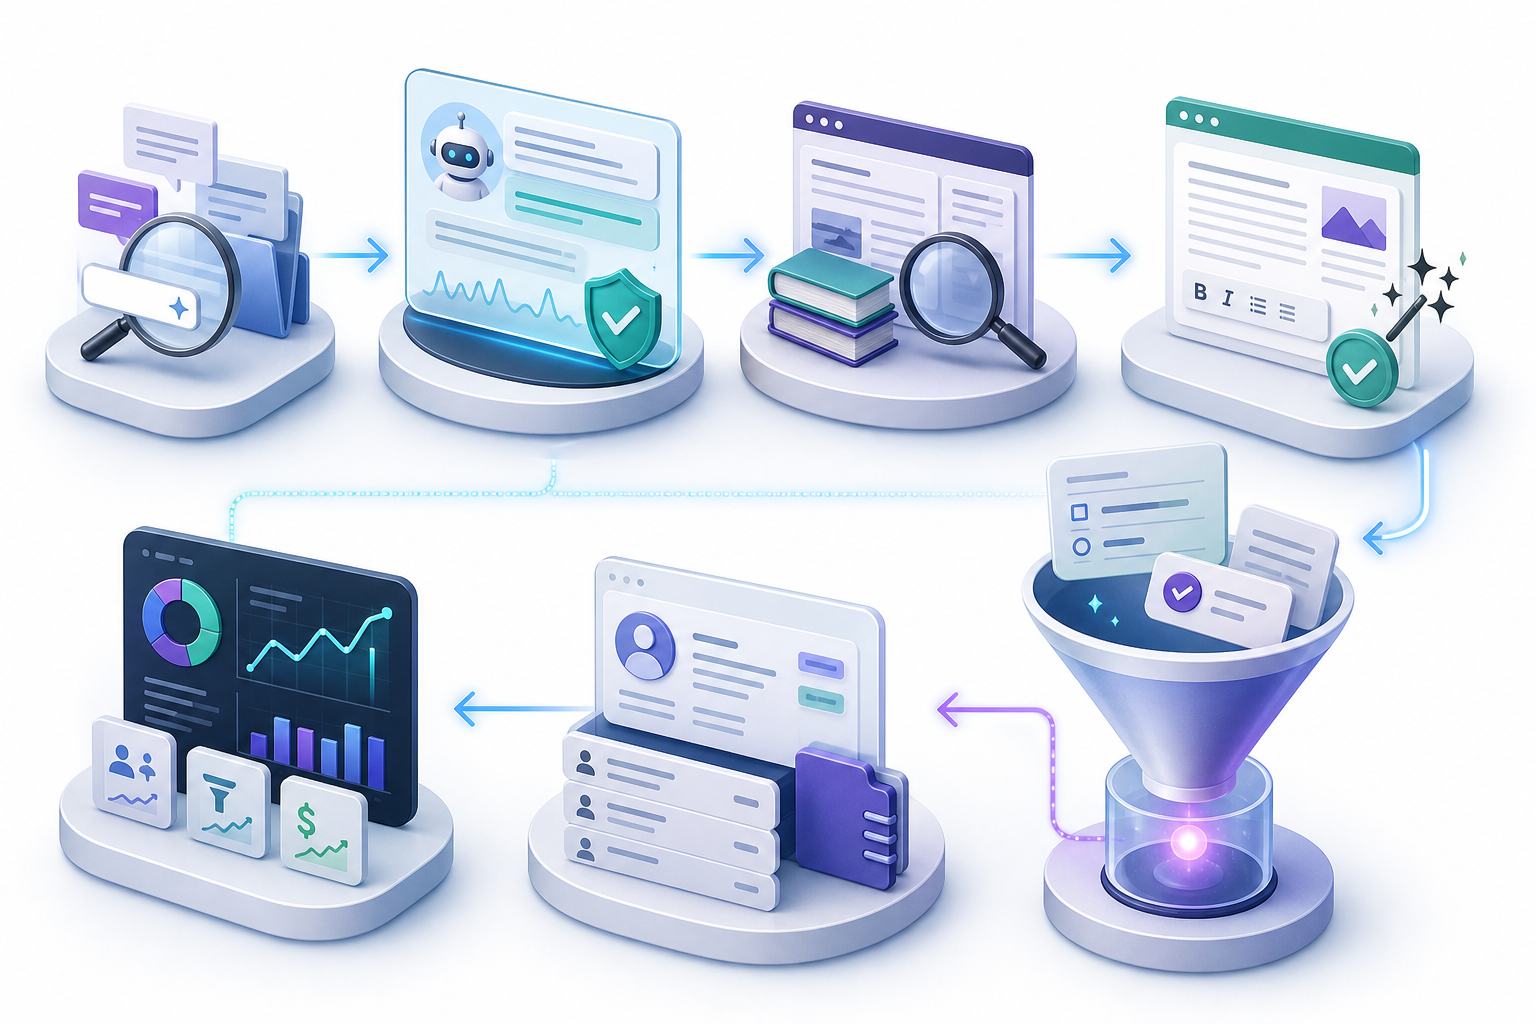
A practical stack has four layers: discovery, observation, improvement, and attribution. Expensive duplication often occurs when teams buy multiple monitoring products but have no process for converting findings into better source material or measurable customer journeys.
Step 1: Establish a conventional search foundation
Use a crawler, Search Console, Bing Webmaster Tools, and an SEO research platform to inventory pages and diagnose access. Confirm that important explanatory content is indexable, rendered correctly, canonicalized, and internally linked. Review structured data for factual consistency, but do not assume schema markup guarantees inclusion in an AI answer.
Create an entity map covering the organization, products, category, experts, audience, use cases, and proof. Names and claims should remain consistent across product pages, documentation, author biographies, profiles, and reputable third-party references. Ambiguous or conflicting facts make reliable synthesis harder.
Step 2: Create a prompt universe
Start with 30 to 100 high-value prompts rather than thousands of loosely relevant questions. Gather them from sales calls, site search, support tickets, customer interviews, paid-search terms, community discussions, and query data. Search volume can inform prioritization, but many valuable conversational prompts will not have dependable volume estimates.
Store a stable core set for trend analysis and a rotating discovery set for emerging language. Tag each prompt by market, persona, problem, use case, funnel stage, and preferred destination. This structure allows the team to see whether visibility is growing among actual buyers rather than on informational questions with little commercial relevance.
Step 3: Monitor answers and sources
Choose one primary GEO tracker and configure the core prompt set across the supported engines. Record the brand, product, competitors, cited pages, cited third parties, answer framing, and accuracy. Set alerts for harmful factual errors, lost citations, significant competitor gains, and changes involving high-intent prompts.
Manually review priority answers each week. Ask whether the recommendation satisfies the prompt, whether a cited source actually supports the generated claim, and whether the answer has omitted a critical constraint. Automated sentiment labels are useful for triage but can miss subtle inaccuracies.
Step 4: Improve the information asset
Prioritize pages that can become useful sources, not pages padded with repetitive keyword variations. Add concise definitions, explicit product capabilities, original data, named methodology, expert review, dates, limitations, comparison criteria, and examples. Use descriptive headings and answer the main question before expanding into nuance.
For example, a page about quiz funnels should explain what a quiz funnel is, who it suits, how branching logic works, which events to measure, and when a static form is preferable. It should distinguish the lead magnet from the sequence after completion. Clear boundaries increase trust and reduce the chance that an AI system recombines the information incorrectly.
GeniuzQuiz builds AI-assisted quiz funnels that collect responses, segment leads, and route users toward relevant outcomes. Teams exploring implementation can review its features, adapt proven templates, and compare pricing before connecting a funnel to campaign and CRM workflows.
Step 5: Strengthen third-party corroboration
Source analysis often reveals that assistants rely on a small set of independent domains for category recommendations. Study why those pages are useful. They may include hands-on testing, transparent criteria, expert quotations, customer experiences, current pricing context, or a broad market comparison.
Do not manufacture reviews or flood low-quality directories. Instead, provide publishers and partners with verifiable product information, original research, expert access, demos, and customer evidence. Correct inaccurate listings where appropriate. The objective is a consistent public evidence trail, not artificial mention volume.
Step 6: Connect visibility to the funnel
Add analytics annotations and preserve referrer information where available. AI traffic may appear under referral, organic, direct, or an emerging source label, depending on the product and browser. Create channel group rules carefully and avoid claiming that all direct traffic came from an assistant.
For a quiz funnel, track landing-page views, quiz starts, completion rate, outcome views, lead submissions, qualification status, booked calls, purchases, and downstream revenue. Compare cohorts from identifiable AI referrals with organic search, Meta ads, email, and other sources. Even a small amount of AI-referred traffic can be meaningful if it arrives with strong problem awareness and converts well.
Step 7: Run a monthly evidence review
Review visibility changes alongside published content, technical fixes, earned mentions, product releases, and changes to the monitored engines. Select a limited number of interventions for the next cycle. This prevents the team from reacting to every fluctuation and creates a defensible record of what appears to work.
Which metrics prove GEO performance?
No universal GEO metric has the stability of an accounting measure. Metrics are best treated as observations from a controlled panel of prompts. Define each formula, retain raw answers, and report sample size with the result.
- Brand mention rate: Answers mentioning the brand divided by eligible answers checked.
- Attributed mention rate: Answers that both mention the brand and link or cite a supporting source divided by eligible answers.
- Citation share: Brand-owned citations divided by all citations in the monitored answer set. Calculate domain-level and page-level versions.
- Prompt coverage: Prompts where the brand appears at least once divided by tracked prompts.
- Recommendation rate: Answers that explicitly recommend or shortlist the brand divided by relevant commercial answers.
- Answer prominence: The brand's location in the answer, such as first recommendation, shortlist inclusion, body mention, or footnote-only citation.
- Source diversity: Number and distribution of independent domains supporting relevant brand or category claims.
- Accuracy rate: Correct monitored claims divided by all monitored claims about the brand.
- Volatility: The frequency with which mentions, recommendations, or citations change across repeated observations.
- AI-assisted conversion rate: Qualified conversions attributed or credibly assisted by identifiable AI visits divided by those visits.
Separate visibility from favorability. A product can be mentioned frequently because answers criticize it, describe an obsolete feature, or position it for the wrong audience. Likewise, a citation can support generic educational information without recommending the product.
Weighting can improve reporting when it is transparent. A high-intent comparison prompt might receive more weight than a broad definition prompt, and a first-position recommendation might receive more weight than a passing mention. Do not hide weighting inside a proprietary score that stakeholders cannot audit.
A useful executive dashboard can show five lines: high-intent mention rate, recommendation rate, attributed mention rate, accuracy rate, and qualified conversions. The operating dashboard beneath it should retain prompt-level evidence, engine filters, source URLs, competitors, and content actions.
Establish a baseline before optimizing. Track the stable prompt set for several cycles, calculate normal variance, and then annotate changes. If mention rate moves from 20% to 24% after a page update but historical observations regularly swing by eight percentage points, there is not yet strong evidence of improvement.
Revenue attribution deserves particular caution. Many AI answers create zero-click awareness, and users may return through branded search or type a URL later. Use self-reported attribution, assisted-conversion paths, CRM notes, and controlled landing pages where practical. Report direct and assisted impact separately.
Where do GEO tools fail or mislead teams?
The largest limitation is answer variability. Generated responses may change because of model updates, retrieval results, user context, location, prompt wording, or randomness. A tracker provides a sample, not a complete census of what every user sees.
Second, vendors may label unlike data with similar terminology. “Share of voice” could mean the proportion of answers containing a brand, the brand's share of all mentions, a weighted prominence score, or estimated market exposure. Ask for the formula and raw records before comparing platforms.
Third, monitoring can create a false impression of causality. A citation gained after a content update may have resulted from a model change, newly indexed third-party article, or ordinary sampling variance. Use annotations and repeated measurements, and avoid promising that one edit caused an answer change.
Fourth, recommendation engines can tempt teams to produce formulaic content. Adding a summary, statistics, or question headings does not automatically make a page authoritative. Unsupported numbers, fake expertise, and shallow comparison tables can damage user trust even if they temporarily increase machine-readable detail.
Fifth, citation tracking does not capture every valuable influence. An assistant may synthesize information from sources that are not visibly linked, rely on internal model knowledge, or mention a brand without sending traffic. Conversely, a linked page may receive clicks but attract people who are not suitable customers.
Sixth, automated sentiment and entity matching can be wrong. Brands with generic names, abbreviations, similarly named competitors, and multiple product lines require manual validation. Configure aliases and exclusions, then inspect false positives before presenting results to leadership.
Finally, tool coverage can lag behind product changes. AI companies alter interfaces, citation formats, browsing behavior, and access policies frequently. A platform may temporarily lose visibility into a surface or reproduce it imperfectly through an API. Maintain a small manual benchmark set so the team can detect a gap between the dashboard and real user experience.
The best defense is triangulation. Combine a GEO tracker, live manual checks, conventional search data, analytics, CRM outcomes, and customer conversations. If multiple evidence sources agree, the conclusion is more reliable. If they conflict, investigate rather than averaging the discrepancy away.
Frequently asked questions
What is the best generative engine optimization tool?
There is no single best GEO tool for every organization. Profound and Scrunch AI may fit enterprise programs, while Peec AI, Otterly.AI, or ZipTie.dev may suit focused monitoring and agency workflows. Semrush, Ahrefs, and SE Ranking can be attractive when teams want AI data near existing SEO work. Evaluate each option with the same prompts, markets, engines, and reporting requirements.
Can I track whether ChatGPT recommends my brand?
Yes, a GEO monitoring platform can repeatedly test relevant prompts and record whether ChatGPT mentions, cites, or recommends the brand. The result is still a sample. Consumer answers can vary by user context, browsing mode, model, and date, so manually verify important prompts and avoid treating a tracked percentage as universal exposure.
How is a GEO tool different from an SEO tool?
An SEO tool typically measures keywords, rankings, links, technical health, and search traffic. A GEO tool measures generated answers, brand inclusion, source citations, competitive recommendations, and answer framing. The categories complement each other: SEO tools diagnose whether information is accessible and authoritative, while GEO tools observe how AI systems synthesize that information.
Do GEO tools measure Google AI Overviews?
Some do, but coverage varies by vendor, country, query set, device, and data collection method. Ask whether the tool captures live AI Overviews, how it handles queries where no overview appears, and whether it stores the generated text and cited URLs. Google Search Console does not provide a complete standalone AI Overview performance report, so combine available search data with dedicated monitoring.
How many prompts should I track for GEO?
A small business can start with 30 to 50 carefully selected prompts. A multi-product or international organization may need hundreds or thousands, segmented by market and audience. Quality matters more than volume. Keep a stable benchmark set for trend analysis and a rotating set for new questions, competitors, product features, and customer language.
Can Google Analytics identify traffic from AI search?
Analytics can identify some visits from assistants when referrer information is passed, but it cannot measure every AI mention or zero-click answer. Configure source groupings for known AI referrals, retain landing-page and conversion data, and review direct traffic cautiously. Add self-reported attribution or CRM fields when knowing how qualified leads discovered the business is important.
Can a GEO tool guarantee citations in ChatGPT or AI Overviews?
No. A tool can reveal patterns, monitor outcomes, and identify useful improvements, but it cannot guarantee selection by an external model. Citation behavior depends on the question, retrieval system, available sources, model policies, freshness, and user context. Be skeptical of vendors or agencies promising permanent placement or guaranteed recommendations.
How often should AI visibility be checked?
Weekly checks are a reasonable starting point for stable commercial prompts. Daily monitoring may be justified during a launch, crisis, migration, or major model change. Monthly reporting can work for leadership, provided the operating team retains more granular observations. Match frequency to decision speed and always preserve enough history to distinguish a real trend from normal volatility.